Loading
Measured, not claimed.
Screen-Time’s own reports for 11 test Reels, as delivered on this site, compared frame by frame with labels of where the product is on screen.
1,931 frames with the product in 2,800; 11 Reels; 9 people. Measured 2026-11-03.
Labels: drafted by two independent Claude vision passes at 5 frames a second, then checked frame by frame by a person on all 11 clips.
Watch the labels against the count- Precision per frame
- 98.4%
- 95% interval 96.7–99.6%
- of the seconds it counted, the share that really showed the product
- Recall per frame
- 91.1%
- 95% interval 70.3–100.0%
- of the seconds the product really showed, the share it counted
F1 94.6% · 95% interval 81.9–99.6% · the two in one figure
| Score, per frame | SAM 3.1 alone | + Muse Spark |
|---|---|---|
| Precision | 95.0% | 98.4% |
| Recall | 99.3% | 91.1% |
| F1 | 97.1% | 94.6% |
The intervals come from resampling whole Reels (100,000 draws, seed 20261103): they show how much the figures depend on which Reels are in the set, not how wrong the labels might be. Recall’s is wide because a Reel where the product was on screen counted nothing (see Where it is wrong).
Check it yourself
Play a Reel and watch the person’s labels and Screen-Time’s count run side by side, frame by frame. Pick any of the 11 rows below to load its Reel.
0:00.0
Michael · LaCroix can
Not Michael K’s Reel
- Labelled by a person
- 0.0s
- Counted by Screen-Time
- 0.0s
seconds so far, of 12.4 s
Whole Reel: 2.6 s labelled, 3.0 s counted; precision 84.8%, recall 100.0%.
Labelled (checked by a person)
Counted (by Screen-Time)
Red is where they disagree: solid where Screen-Time counted a frame the person did not label (an over-count), outlined where it missed a labelled frame. Per frame, at 15 frames a second.
- Labelled
- 21.3 s
- Measured
- 21.7 s
- Precision
- 98%
- Recall
- 100%
- Labelled
- 16.5 s
- Measured
- 16.5 s
- Precision
- 100%
- Recall
- 100%
- Labelled
- 14.0 s
- Measured
- 14.0 s
- Precision
- 98%
- Recall
- 99%
- Labelled
- 13.7 s
- Measured
- 14.5 s
- Precision
- 94%
- Recall
- 100%
- Labelled
- 13.3 s
- Measured
- 13.3 s
- Precision
- 100%
- Recall
- 100%
- Labelled
- 12.1 s
- Measured
- 12.1 s
- Precision
- 100%
- Recall
- 100%
- Labelled
- 12.0 s
- Measured
- 12.0 s
- Precision
- 100%
- Recall
- 100%
- Labelled
- 11.8 s
- Measured
- 11.8 s
- Precision
- 100%
- Recall
- 99%
- Weakest precisionNot Michael K’s Reel
- Labelled
- 2.6 s
- Measured
- 3.0 s
- Precision
- 85%
- Recall
- 100%
- Weakest recallMuse Spark could not confirm the product, so none was counted; the report flags it
- Labelled
- 11.2 s
- Measured
- 0.0 s
- Precision
- –
- Recall
- 0%
- Only a look-alike in shot, must count 0
- Labelled
- 0.0 s
- Measured
- 0.0 s
- Precision
- –
- Recall
- –
What Muse Spark adds
The same runs, scored twice: once counting every object SAM 3.1 tracked for the prompt, once counting only the objects Muse Spark confirmed as the brand’s product. No model was run again for this.
| Per frame | SAM 3.1 alone | + Muse Spark |
|---|---|---|
| Precision | 95.0% | 98.4% |
| Recall | 99.3% | 91.1% |
| F1 | 97.1% | 94.6% |
| Avg. error per Reel | 0.5 s | 1.1 s |
| Seconds on Reels without the product | 4.2 s | 0.0 s |
Muse Spark changed the count on 2 of the 11 Reels.
- On George’s Reel Muse Spark could not confirm the can SAM 3.1 tracked for 11.0 s, so it counted 0.0 s against 11.2 s labelled; the report holds the fee and flags it for a person to look at.
Object by object
Each object was judged by Claude from crops of the earlier runs (our zoomed edit of George’s Reel among them) as the product or something else, and matched to these runs by track number: 12 could be judged.
The intervals are exact (Clopper-Pearson) 95% intervals: with 12 objects they are wide.
| Object check | Correct | Look-alikes counted | Products missed |
|---|---|---|---|
| Muse Spark 1.3 (hosted) | 11 of 1262–100% | 0 | 1unclear |
| SAM 3.1 alone (every tracked object counts) | 10 of 1252–98% | 2 | 0 |
Meta’s open-weight Muse Spark Open called 10 of 12 correctly (0 look-alikes counted, 2 real cans called unclear), measured 2026-11-03 on crops from the earlier runs, which used our zoomed edit of George’s Reel; it has not been run on the Reels as delivered.
Pay or hold
Pay or hold on the on-screen term (at least 3.0 s in total) agrees with the labels on 9 of 11 Reels.
9 of 11Reels agree with the labels
Where they differ
- George: 11.2 s labelled, 0.0 s counted, so the labels say pay and the report says hold.
- Michael (not Michael K): 2.6 s labelled, 3.0 s counted, so the labels say hold and the report says pay.
The spoken-name and ad-disclosure terms have no independent labels yet, so they are not scored here.
The captions on these Reels were burned in by the builder from each Reel’s own speech (Voice Transcribe), so the on-screen disclosure check is not independent of the spoken one either.
Where it is wrong
The lowest precision and the lowest recall in the test set. Watch either Reel in the player above.
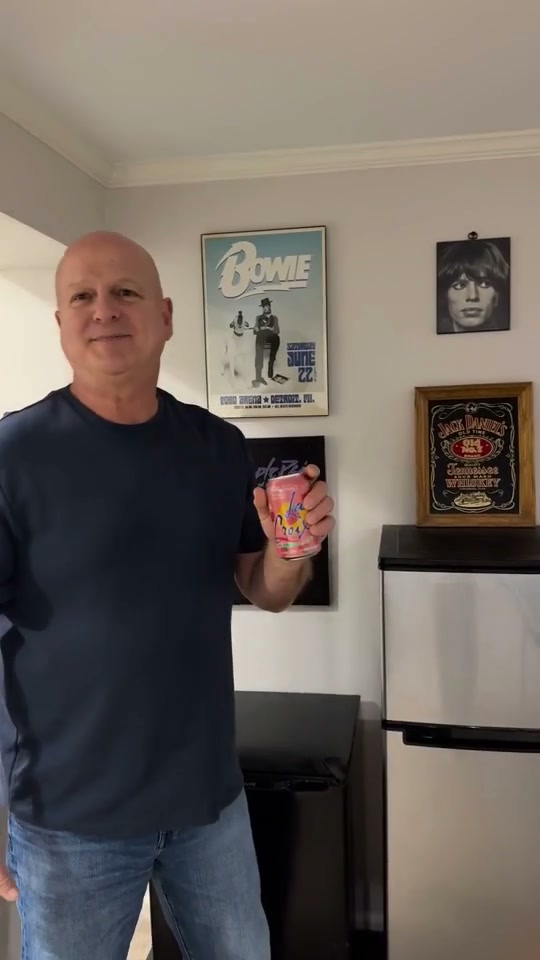
Michael (not Michael K) · LaCroix can
Counted more than was there
Precision 84.8%: 0.4 s counted that the labels mark as not on screen (labelled 2.6 s, counted 3.0 s).
The lowest precision in the test set. Over-counting is the costly error: it would pay for screen time the brand did not get. The contract needs 3.0 s: by the labels this Reel should hold, and the report says pay. The report flags it for a person to look at before paying or holding.
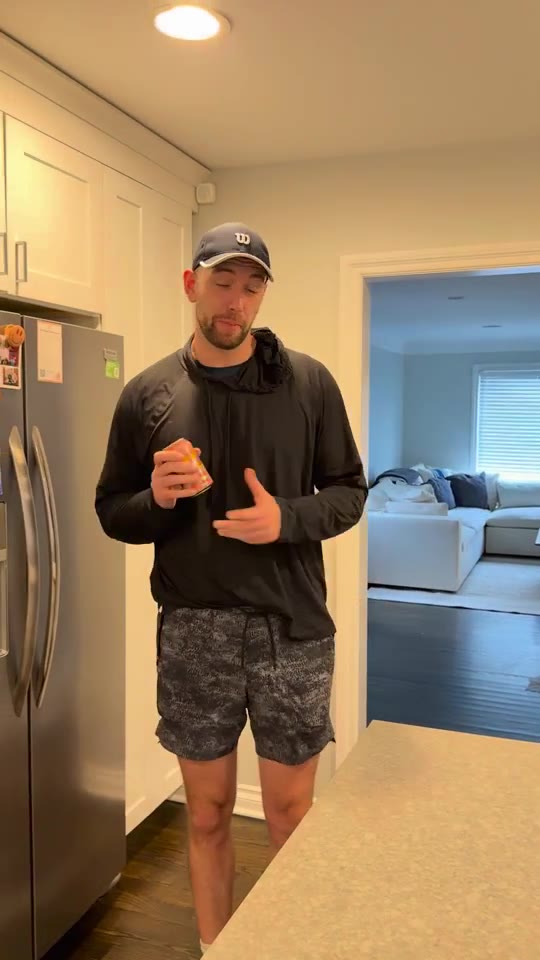
George · LaCroix can
Missed all of it
Recall 0.0%: 11.2 s of real screen time not counted (labelled 11.2 s, counted 0.0 s).
The lowest recall in the test set. Here the report under-counts, so the brand sees less screen time than it got, not more. Muse Spark could not confirm that the tracked object was the product (it called it unclear), so none of it was counted. The contract needs 3.0 s: by the labels this Reel should pay, and the report says hold. The report flags it for a person to look at before paying or holding.
Contract reading (Muse Spark)
30 plain-English clauses, each read 6 times: 21 of the 21 with one right reading were read exactly every time.
- Clauses with one right reading: 21 of 21 exact in every reading, 0 misread (a wrong rule), 0 left for a person.
- Clauses the video cannot settle: 9 of 9 refused in every reading, so a person checks them; turned into a rule 0 times.
- The terms of this site's campaigns: 3 of 3 exact in every reading.
muse-spark-1.3, measured 2026-11-04, $0.34 for the whole eval.
How it was measured
- Analysis rate
- Every video is re-encoded to 15 fps before SAM 3.1, and SAM tracks every one of those frames. Scores compare those 15 fps frames with the labels; the labels themselves were judged on every 3rd frame and each judgement stands for that frame and the next two.
- Runs
- The scored reports are the ones this site shows for these Reels (one run each, kept in the repository under data/runs), so a report and its row here are the same run.
- Labels
- Two independent Claude vision passes over frame-numbered grids at 5 frames a second, kept where both agree, or where one is certain and the other unsure. The look-alike Reel was then corrected by one Claude pass at full resolution. A person then checked every clip frame by frame in the labelling tool. The test set includes 1 Reel with only a look-alike in shot, which must count 0 seconds.
- Scoring
- Per frame: a frame counts when the pipeline says the product is visible in it. Precision is the share of counted frames that were right; recall is the share of real frames that were counted.
- Not yet measured
- How much the product photo adds on its own: runs with and without it have not been compared on the same clips.
- History
- Until Nov 4 this page scored a zoomed edit of George’s Reel that we made (2.3x, following the can); it now scores the Reel as delivered. George’s labels were drawn on that zoomed edit; the zoom follows the can, so on the wide cut they can only miss frames.
See it measure a real video, live.